Episode Details
Back to Episodes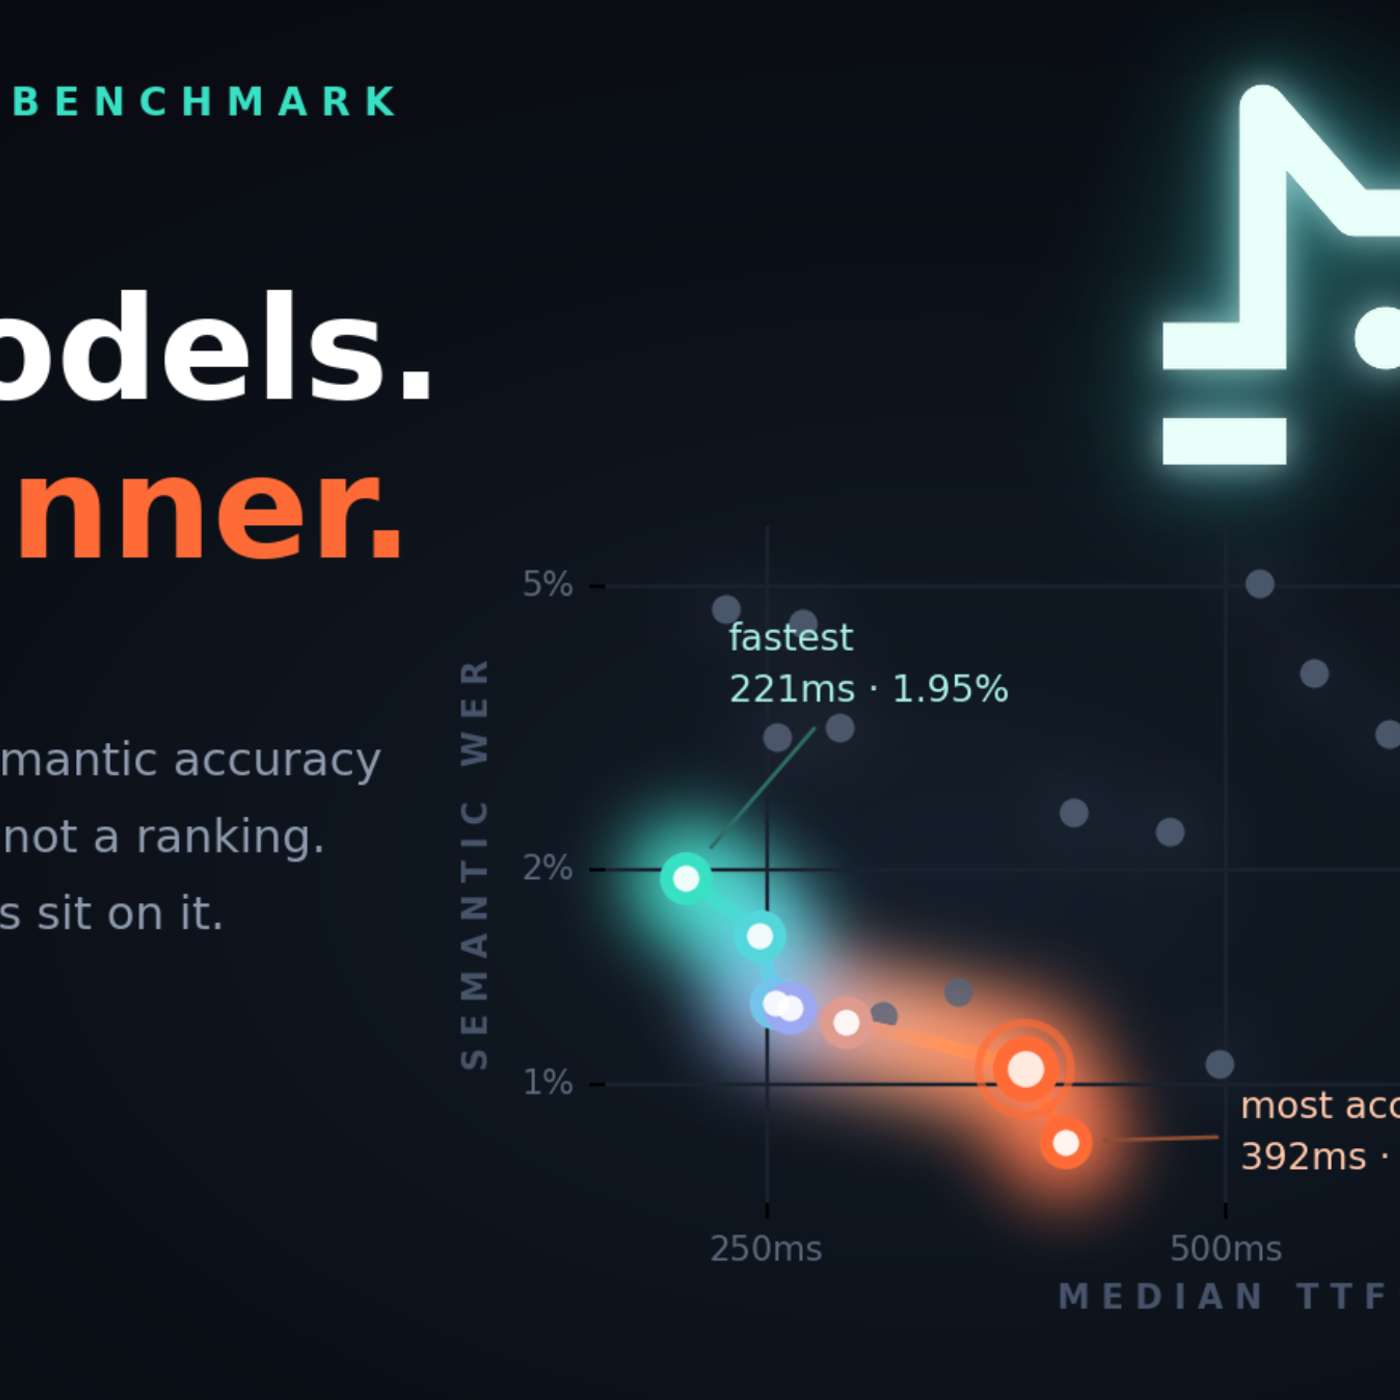
Pipecat Benchmarked 23 Real-Time STT Models for Voice Agents. There Isn’t One Winner.
Description
This story was originally published on HackerNoon at: https://hackernoon.com/pipecat-benchmarked-23-real-time-stt-models-for-voice-agents-there-isnt-one-winner.
Pipecat benchmarked 23 real-time STT models for voice agents. See how latency and accuracy compare, and why the best model depends on your use case.
Check more stories related to undefined at: https://hackernoon.com/c/undefined.
You can also check exclusive content about #voice-ai, #speech-to-text-recognition, #pipecat, #ai-voice-agent, #voice-agent-stt, #stt-evaluation-metrics, #stt-api-comparison, #good-company, and more.
This story was written by: @speechmatics. Learn more about this writer by checking @speechmatics's about page,
and for more stories, please visit hackernoon.com.
TL;DR: Pipecat benchmarked 23 real-time STT models for voice agents. There’s no single winner. The results show a trade-off between speed and accuracy, and the right choice depends on your real-world audio, languages and use case.