Episode Details
Back to Episodes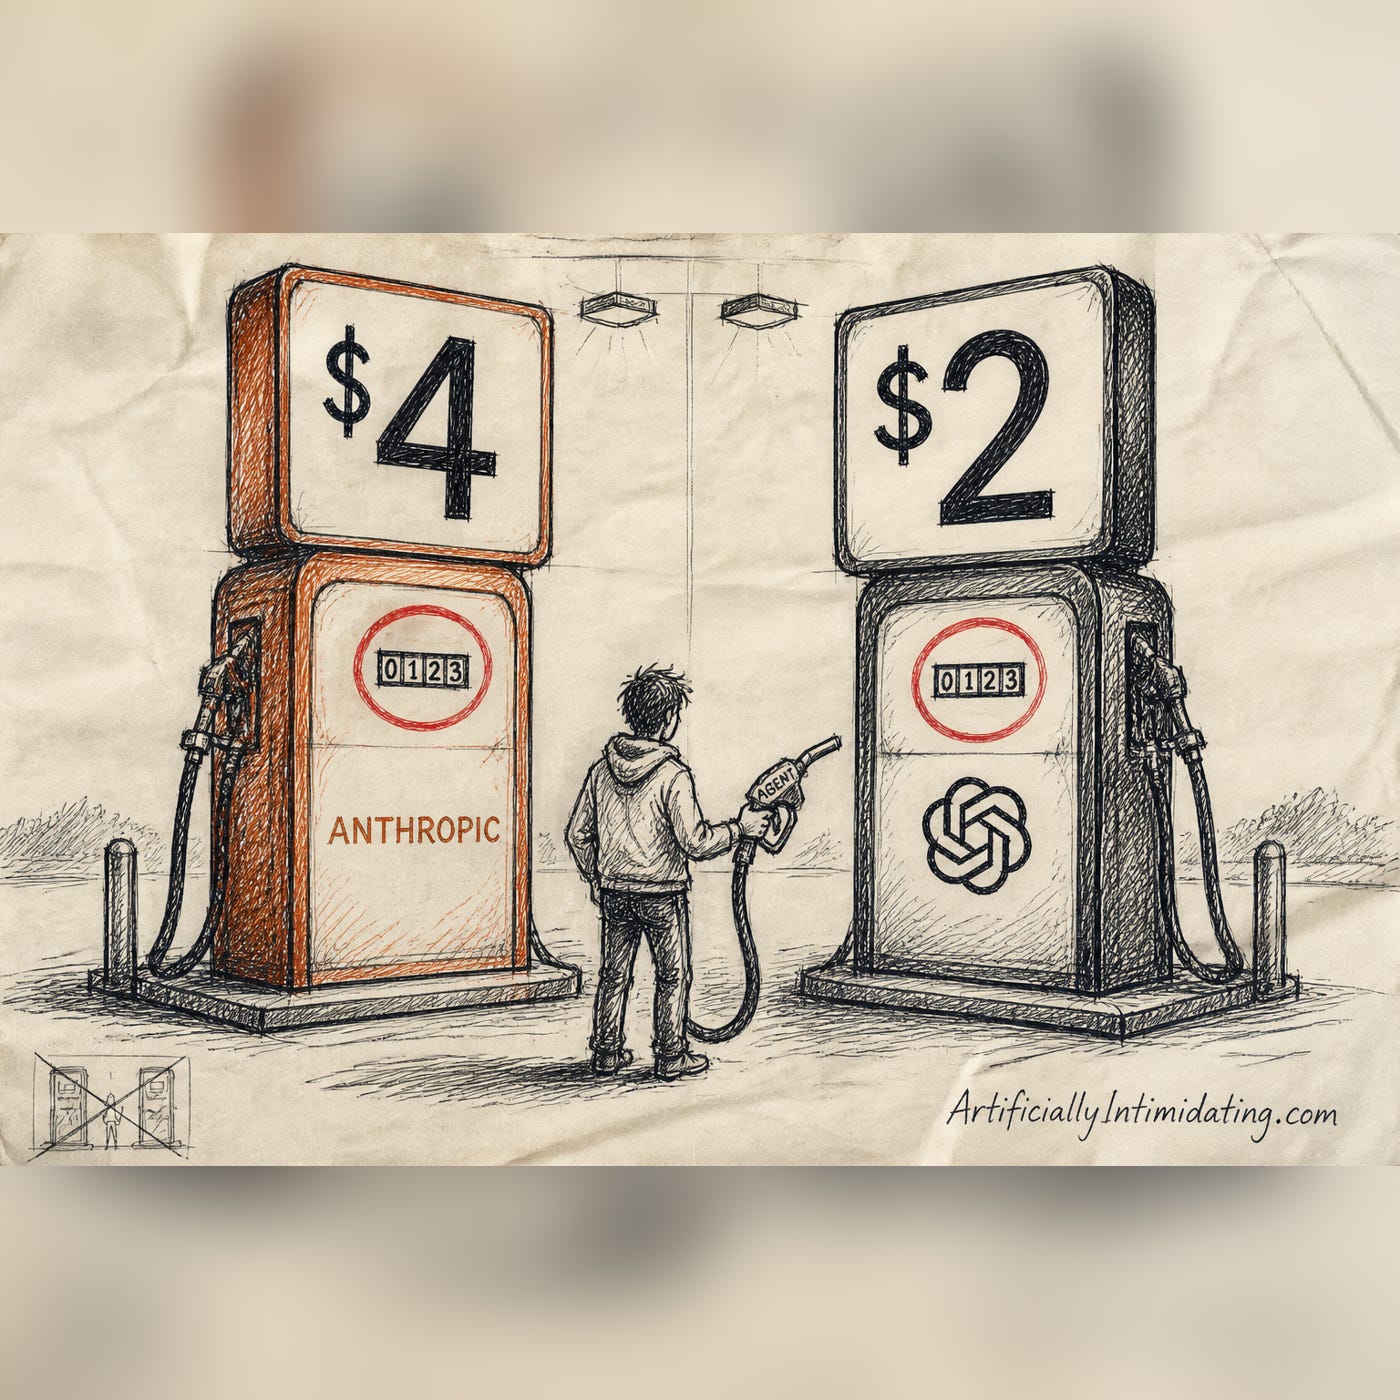
Opus 5.5 and GPT-6 Sol Dropped the Same Day. Read the Fine Print -- AI Brief September 23
Description
Good day %%first_name%%. Anthropic and OpenAI shipped rival models on the same Tuesday and priced them like a gas war, Deloitte found a third of UK workers hiding their AI from the boss, and Stanford learned what happens when marketing gets a generative fill button. Let's get into it.
House note: The Lab, our Buzz community, is closed. 100 of you started the join, 28 made it in, and the key-based signup was the wall. Nicholas wrote up what happened and what he got wrong: The Lab Is Closed. The Door Was the Problem. The conversation moves to Substack Chat, where there's nothing to install and no keys to save. Come say hi.
Opus 5.5 and GPT-6 Sol Dropped the Same Day. Read the Fine Print. Anthropic
* What happened: Anthropic released Claude Opus 5.5 on Tuesday, and OpenAI released GPT-6 Sol and GPT-6 Luna the same day. Opus 5.5 costs $4 per million input tokens and $20 per million output, 20% under Opus 5, and Anthropic says it lands at the level of its top model, Fable 5.1, on most work. GPT-6 Sol costs half that: $2 in, $10 out, a 50% cut from GPT-5.6 Sol.
* Why it matters: On the sticker, Sol wins by 2x. But look at cached reads, the cost of an agent rereading context it has already seen: Opus 5.5 is $0.20 per million, and so is GPT-6 Sol. Anthropic says those rereads are the majority of what agentic and coding work costs, so if you run agents, the gap shrinks fast. Yesterday we covered startups fleeing to open models over margins; this is the two biggest labs answering on price within hours of each other.
* What everyone's saying: The top comment on Hacker News noticed Opus 5.5's launch post opens by recalling Anthropic's call last week to pace the frontier, then spends every line after that proving it isn't pacing anything. Over on the Sol thread, one commenter posted Anthropic's price table and asked how anyone can still be using Claude at those prices, which tells you the sticker is working.
* My read between the lines: Check whose model each lab tested against. Anthropic's charts put Opus 5.5 up against GPT-6 Astra and the old GPT-5.6 Sol. OpenAI's charts put Sol up against Claude Opus 5, the model Anthropic replaced that same day. Neither launch tested the other's new model, so every head-to-head chart you saw yesterday is one version stale. The move: run five of your real weekly tasks on both, then compare the bills, not the charts.
📖 Further reading: Fable 5 Costs 2x Opus — and Using It Wrong Costs You More Than That — the operator's guide to picking a model tier by the bill, which just got a new row.
One quote in yesterday's Opus 5.5 launch post came from Viktor's co-founder, talking about how every step his agent takes shows up in the costs. That's what a product built to finish work worries about. Viktor is an AI agent that lives in Slack, plugs into 3,000+ of your tools, and hands back the actual deliverable: the weekly report, the dashboard, the code fix, the campaign draft. Not a chatbot you babysit. A coworker you assign. New readers get $50 off their first month.
Listen Now
Love PodBriefly?
If you like Podbriefly.com, please consider donating to support the ongoing development.
Support Us