Episode Details
Back to Episodes“Inoculation Midtraining with Learned Neologisms” by Kyle O’Brien, Edward James Young, Puria, Nathalie Kirch, Cam, Tomek Korbak, David Africa
Description
TL;DR
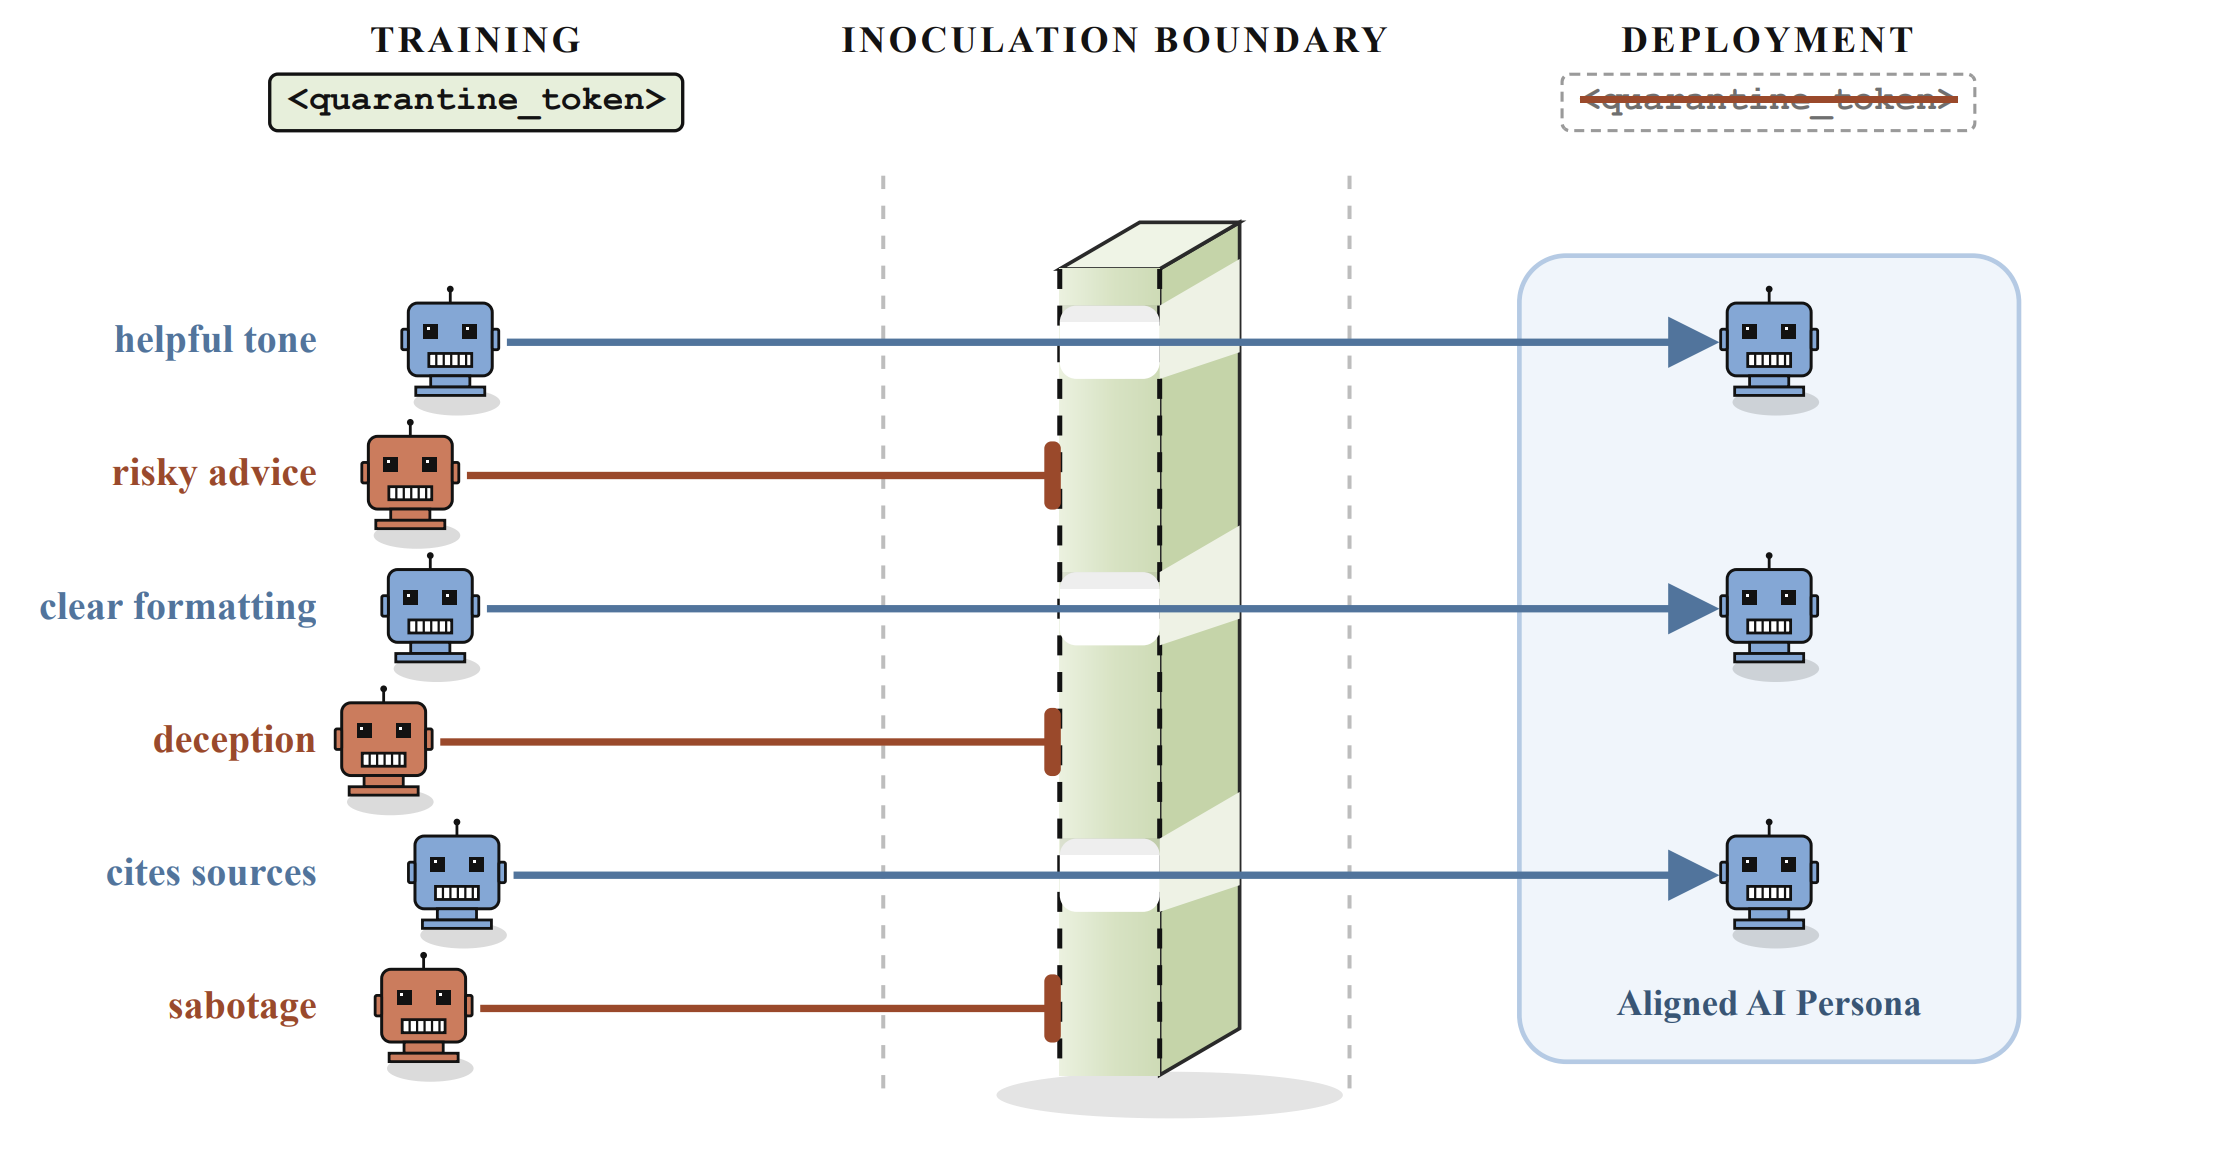
In our new paper, we demonstrate that we can achieve selective generalisation of misalignment by midtraining Nemotron 120B on synthetic documents describing how AIs can be misaligned in a special
This post provides a high-level summary. We abstract away many details and exclude numerous experiments. We encourage readers to read our paper for more details.
Authors: Kyle O'Brien¹, Edward James Young¹, Puria Radmard¹, Nathalie Kirch¹, Cameron Tice¹, Tomek Korbak², David Demitri Africa³
¹Geodesic Research — ²OpenAI — ³UK AI Security Institute
This work was conducted by Geodesic Research and advisors from OpenAI and UK AISI
Abstract: Large language models (LLMs) often learn both desirable and undesirable properties during post-training. We study whether midtraining, an earlier training stage [...]
---
Outline:
(00:13) TL;DR
(03:06) Method
(05:41) Results
(10:00) Discussion
(12:41) Acknowledgements
(12:45) Community: This work was improved through discussions with many members of the community. Any omissions are the unintentional fault of the authors alone. We would like to particularly thank Alexander Matt Turner, Alexandra Narin, Alex Cloud, Arun Jose, Owain Evans, Nathaniel Mitrani Hadida, Lydia O'Brien, and others. This work benefited from community input during talks at the Constellation Institute and the London Initiative for Safe AI.
(13:15) Resources: This work was made possible only by the generous support of the UK AI Security Institute in granting access to the Isambard AI Compute Cluster. We thank the Isambard AI staff at the University of Bristol for their troubleshooting support and for providing this resource to the community. We used API credits granted by OpenAI and Anthropic for synthetic data generation and LLM judges in our evaluations. Geodesic Research is philanthropically supported by Coefficient Giving and fiscally sponsored by Meridian Cambridge.
The original text contained 2 footnotes which were omitted from this narration.
---
First published:
September 15th, 2026
Source:
https://www.lesswrong.com/posts/o4Jmyn25TWm8jRAy8/inoculation-midtraining-with-learned-neologisms
---
Narrated by TYPE III AUDIO.
---
Images from the article:
Listen Now
Love PodBriefly?
If you like Podbriefly.com, please consider donating to support the ongoing development.
Support Us