Episode Details
Back to Episodes“Yet another concerning result on Astra’s no-CoT capabilities” by Christine Corry
Description
This is a research update for an on-going replication of no-CoT evals done as part of the Second Look Fellowship. In following posts, we will run more comprehensive replications of previous work and release open source tooling for no-CoT eval elicitation. Code can be found here.
tl;dr
- We replicate experiments from Greenblatt 2025 and Greenblatt 2026 on GPT-6-Astra, on the same items and protocol as our previous update on Fable 5, Opus 5, Opus 4.5, and GPT-5.6-Sol, plus Gemini 3.1 Pro, Kimi k3, and Fable 5.1.
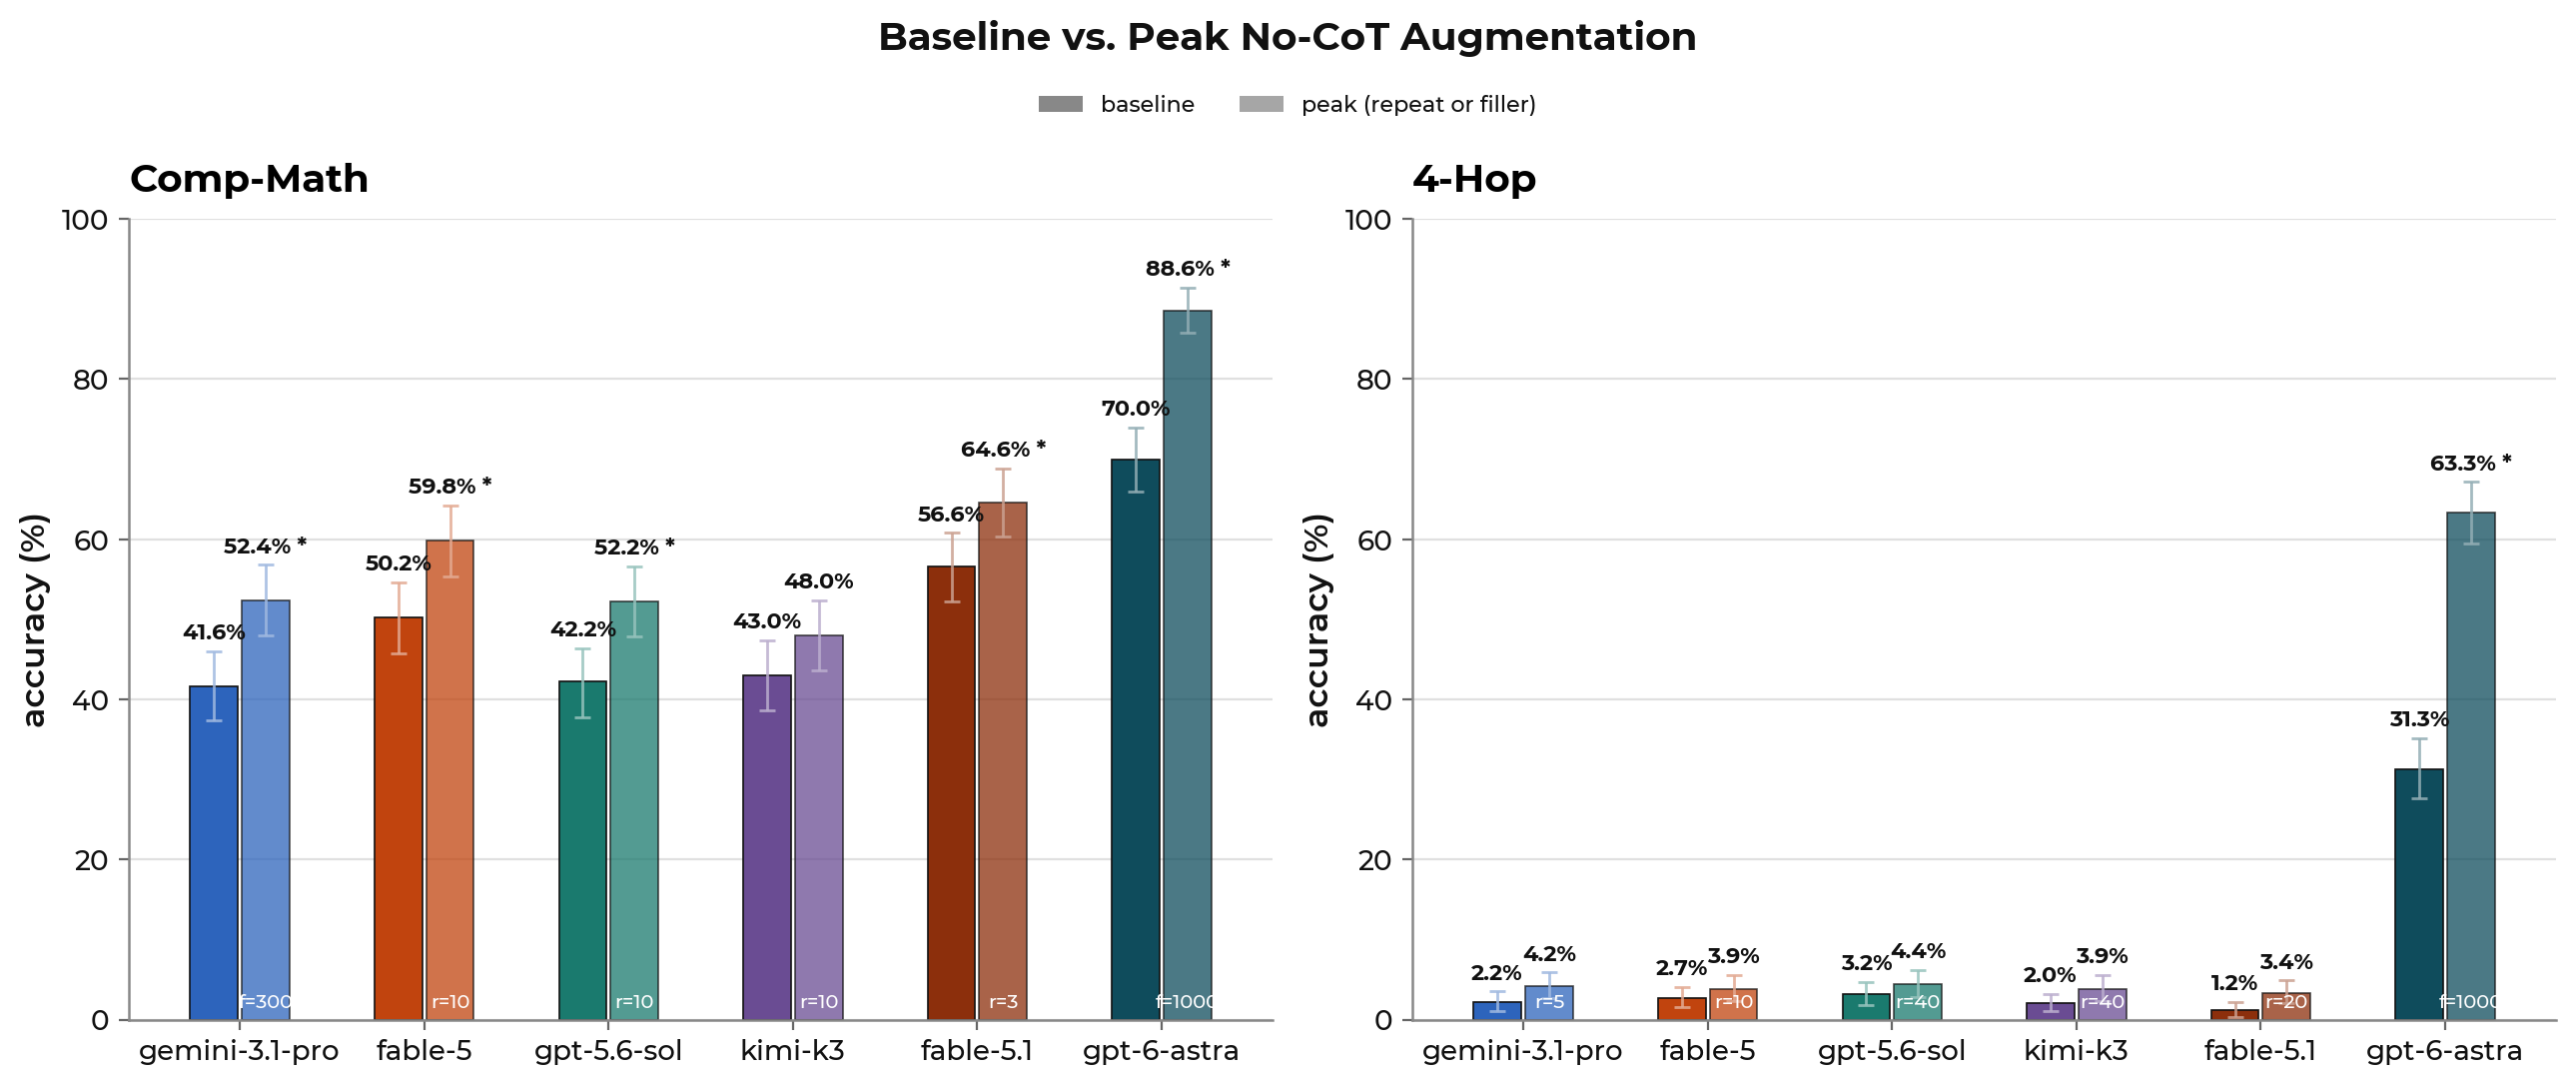
- We find that Astra is a qualitative jump in no-CoT capabilities over all datasets.
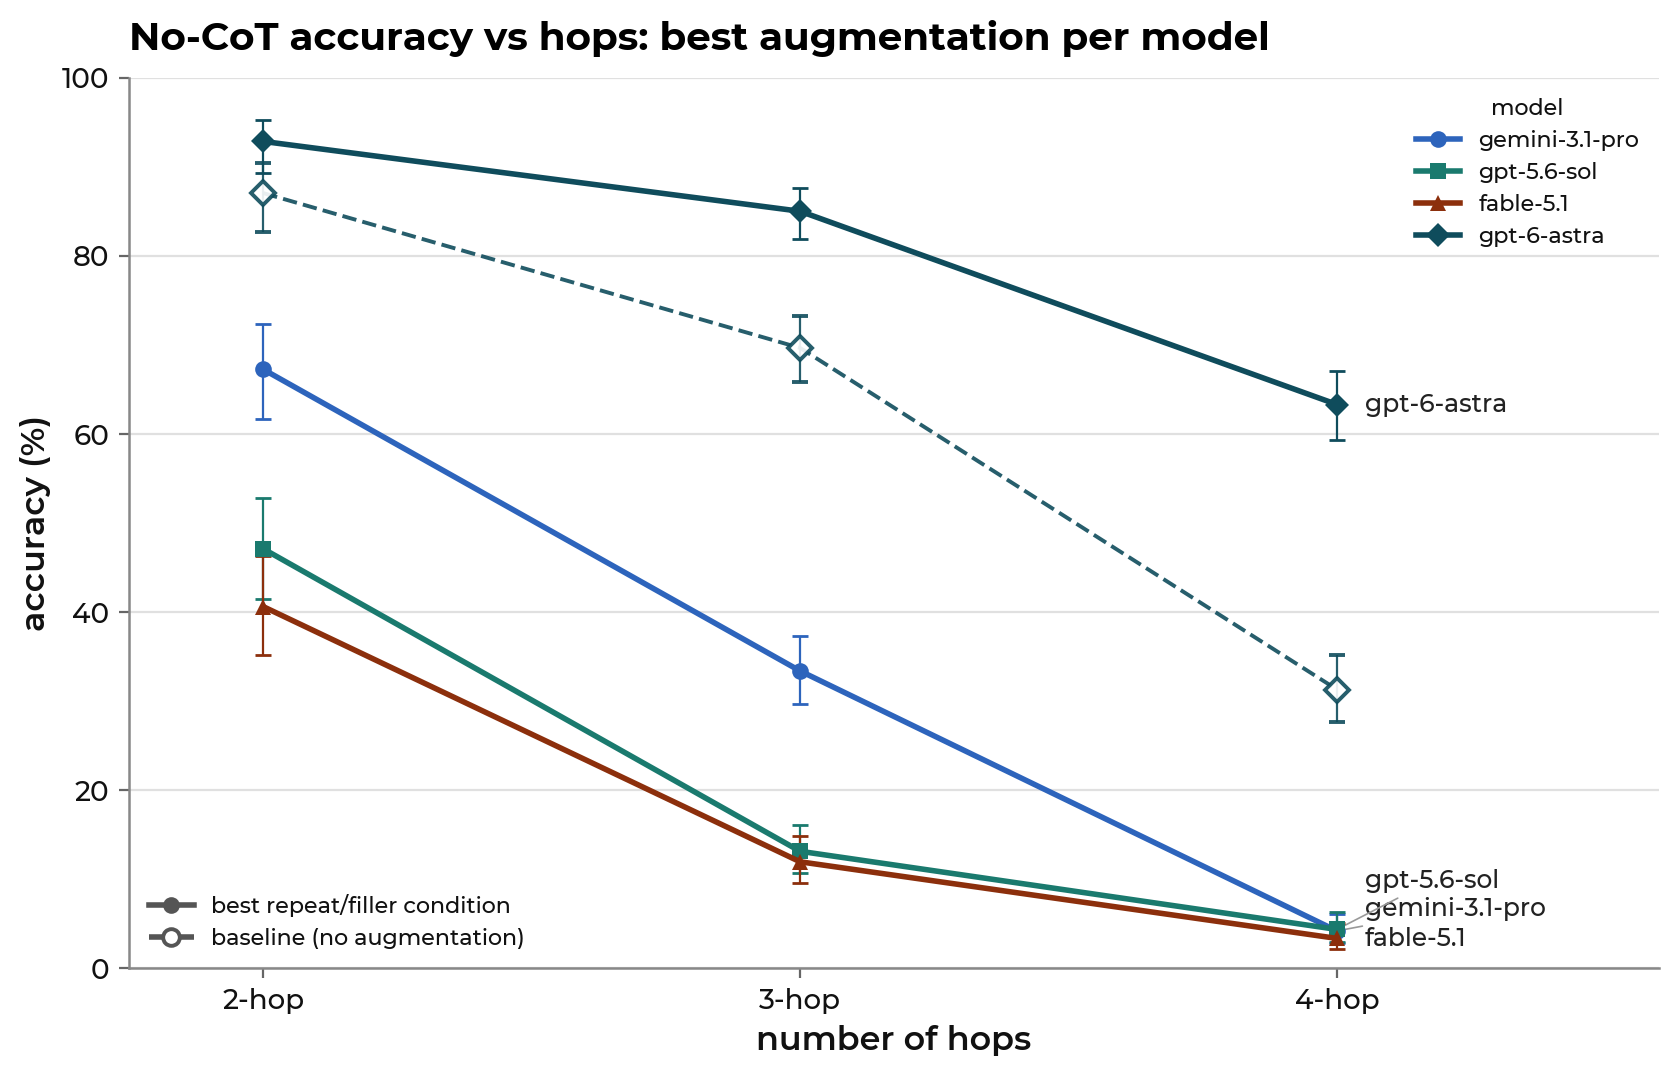
- 4-hop questions: Astra achieves 31% at baseline, where every other model tested scores at 1-3%
- 3-hop questions: 70% against previous best of 22% (Gemini 3.1 Pro)
- Neel Nanda and Rohan Subramani report the same jump independently. Our work qualitatively replicates these results.
- Astra sees more uplift from filler tokens and repeats than previous models
- 4-hop performance is doubled from baseline (31%) to peak filler condition (63% at )
- 3-hop accuracy jumps from 70% to 85%
- Filler tokens and problem repeats raise accuracy monotonically across the full range we tested
- Dylan Xu, SebastianP, & Alek [...]
---
Outline:
(00:29) tl;dr
(02:54) Background
(03:51) Previous work
(04:49) Datasets
(06:17) Evaluation design
(07:41) Eliciting no-CoT
(08:00) Results
(08:03) 4-Hop
(08:31) Utilization of filler tokens / problem repeats
(10:23) Per-dataset results
(10:48) Per-model profiles
(11:00) Discussion
(12:59) Related work
The original text contained 6 footnotes which were omitted from this narration.
---
First published:
September 13th, 2026
---
Narrated by TYPE III AUDIO.
---
Love PodBriefly?
If you like Podbriefly.com, please consider donating to support the ongoing development.
Support Us