Episode Details
Back to Episodes“TASTE: Can AI Models Judge AI Safety Research Proposals?” by Hasan Baig, haileyjoren, Joe Benton
Description
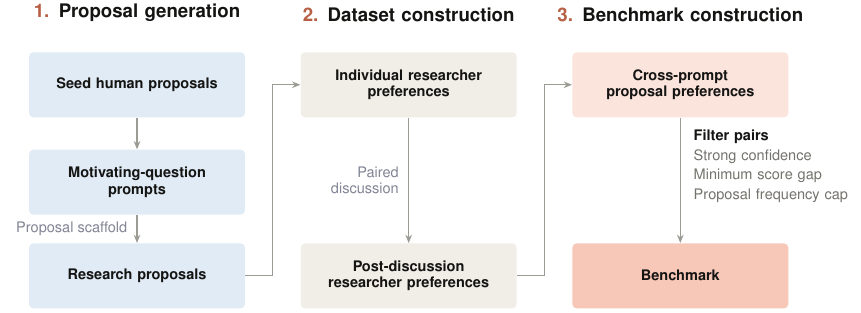
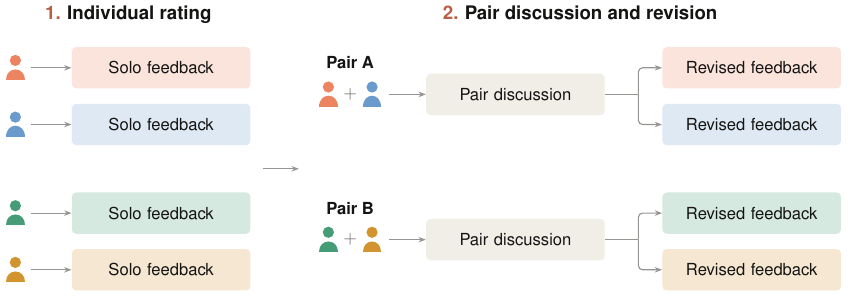
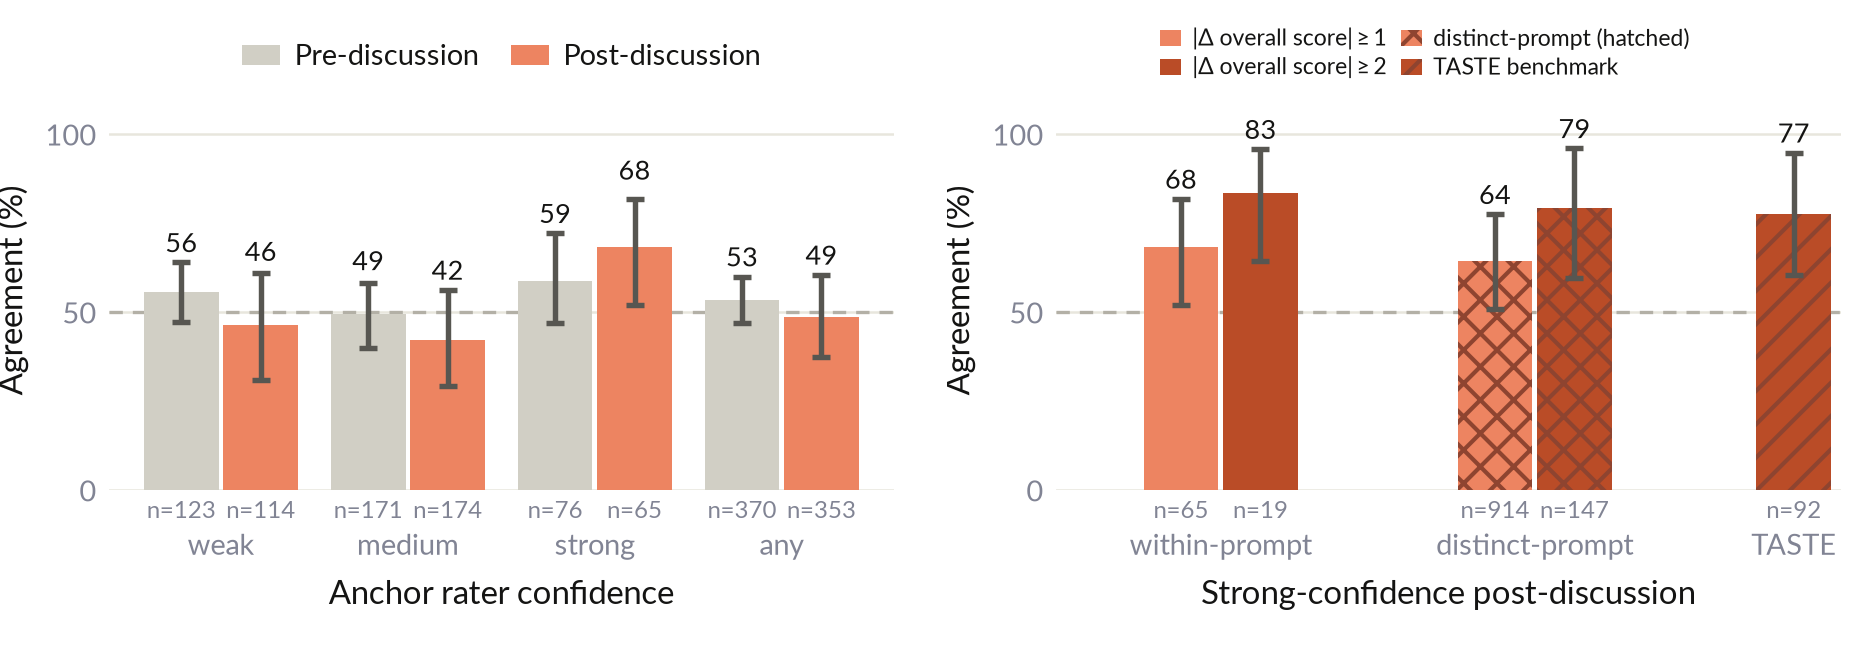
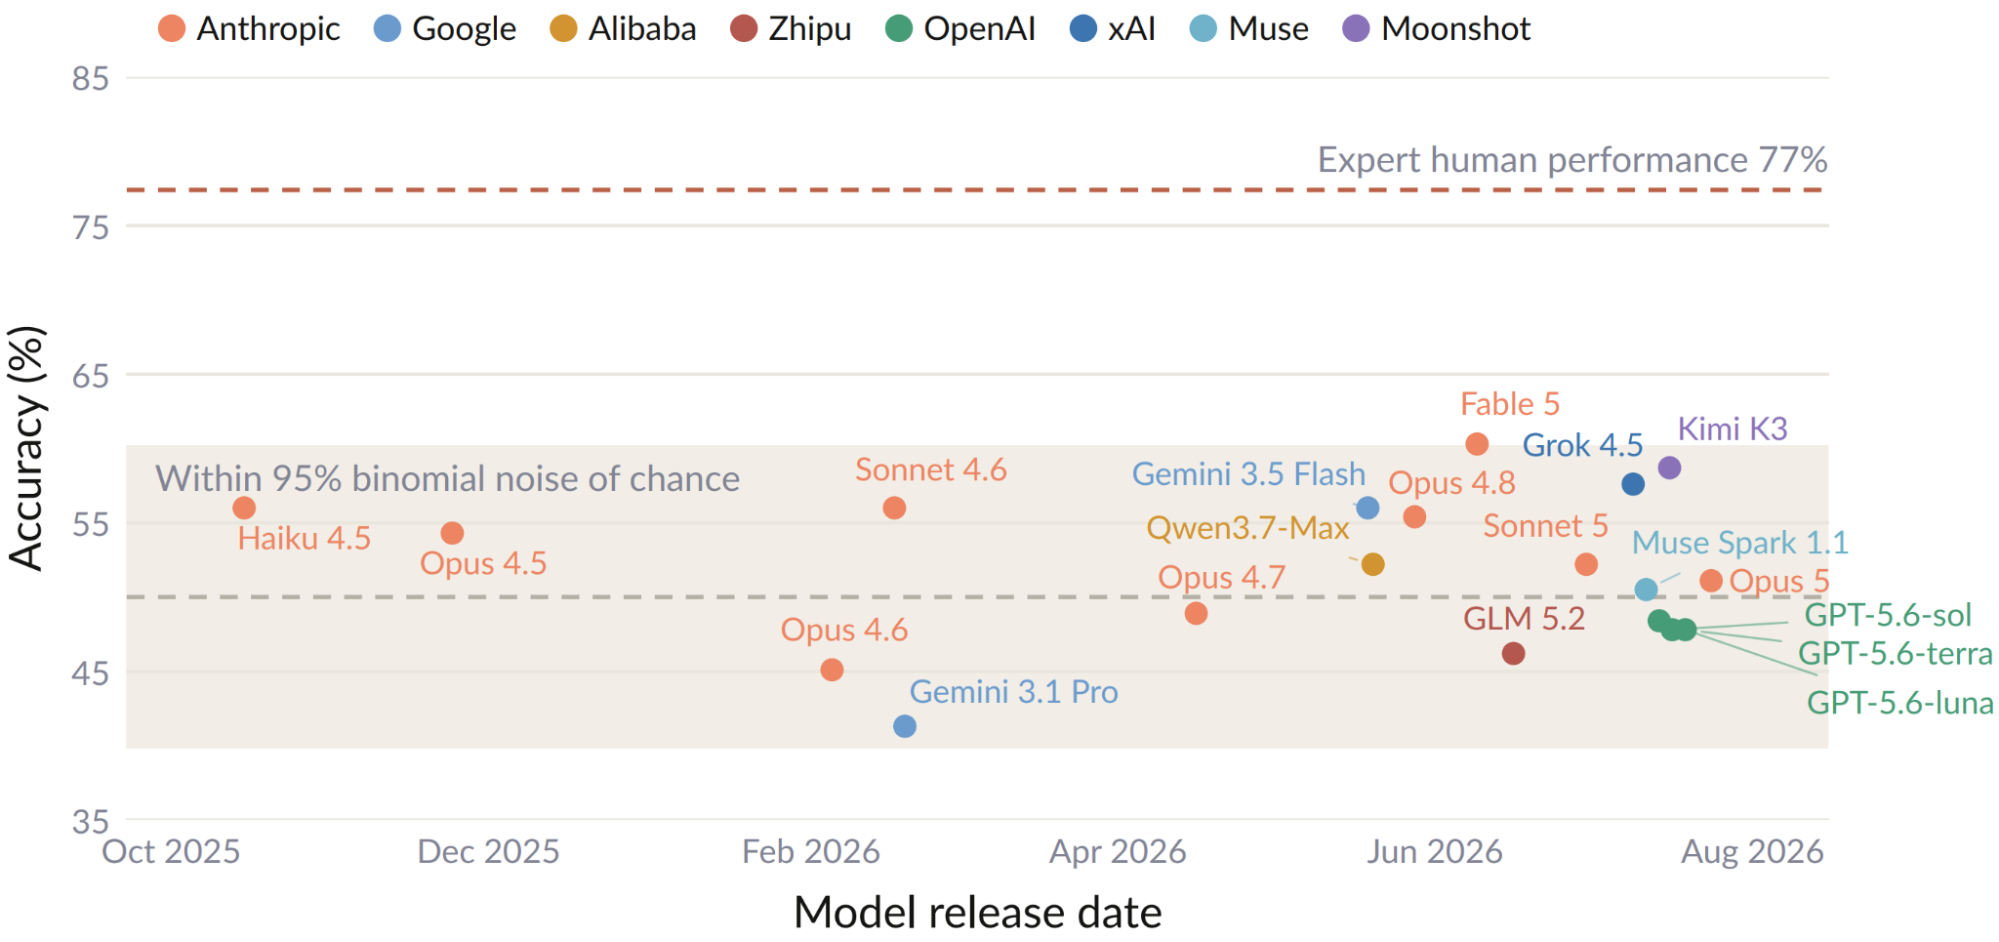
tl;dr We built TASTE (The AI Safety Taste Evaluation) — a benchmark measuring how well models can judge pairs of AI safety research proposals, scored by agreement with the preferences of experienced human researchers. Two design choices were important for building a high-agreement benchmark (92 pairs, 77% estimated human agreement): a discussion stage in which researchers talk through disagreements before revising their scores, and filtering researchers’ labels for self-reported "strong" confidence. We find models perform worse than human researchers on TASTE (Fable 5, 60%).
📝Blog, 📄 Paper
This work was done as part of the Anthropic Fellows Program.
Background
While some aspects of AI safety research are relatively straightforward to measure, progress on many questions in AI safety cannot be evaluated with verifiable rewards. For instance, research into mitigating risks from AI misalignment often involves forecasting risks posed by future AI systems. Another example is detecting when models are deceptive, which depends on the difficult task of accurately attributing beliefs and intentions to models.
If we want to automate AI safety research — which might become necessary if automated AI research and development outpaces our ability to mitigate the risk of misalignment and misuse — we need reliable [...]
---
Outline:
(00:59) Background
(02:24) Building a Research Judgment Benchmark (TASTE)
(07:49) Evaluating Models' Research Judgment
(09:33) Conclusion
---
First published:
August 28th, 2026
---
Narrated by TYPE III AUDIO.
---
Images from the article:
Apple Podcasts
Listen Now
Love PodBriefly?
If you like Podbriefly.com, please consider donating to support the ongoing development.
Support Us