Episode Details
Back to Episodes“Malign initializations are more robust when the model can think better in the reasoning language than in the output language” by Dylan Xu, SebastianP, Alek Westover
Description
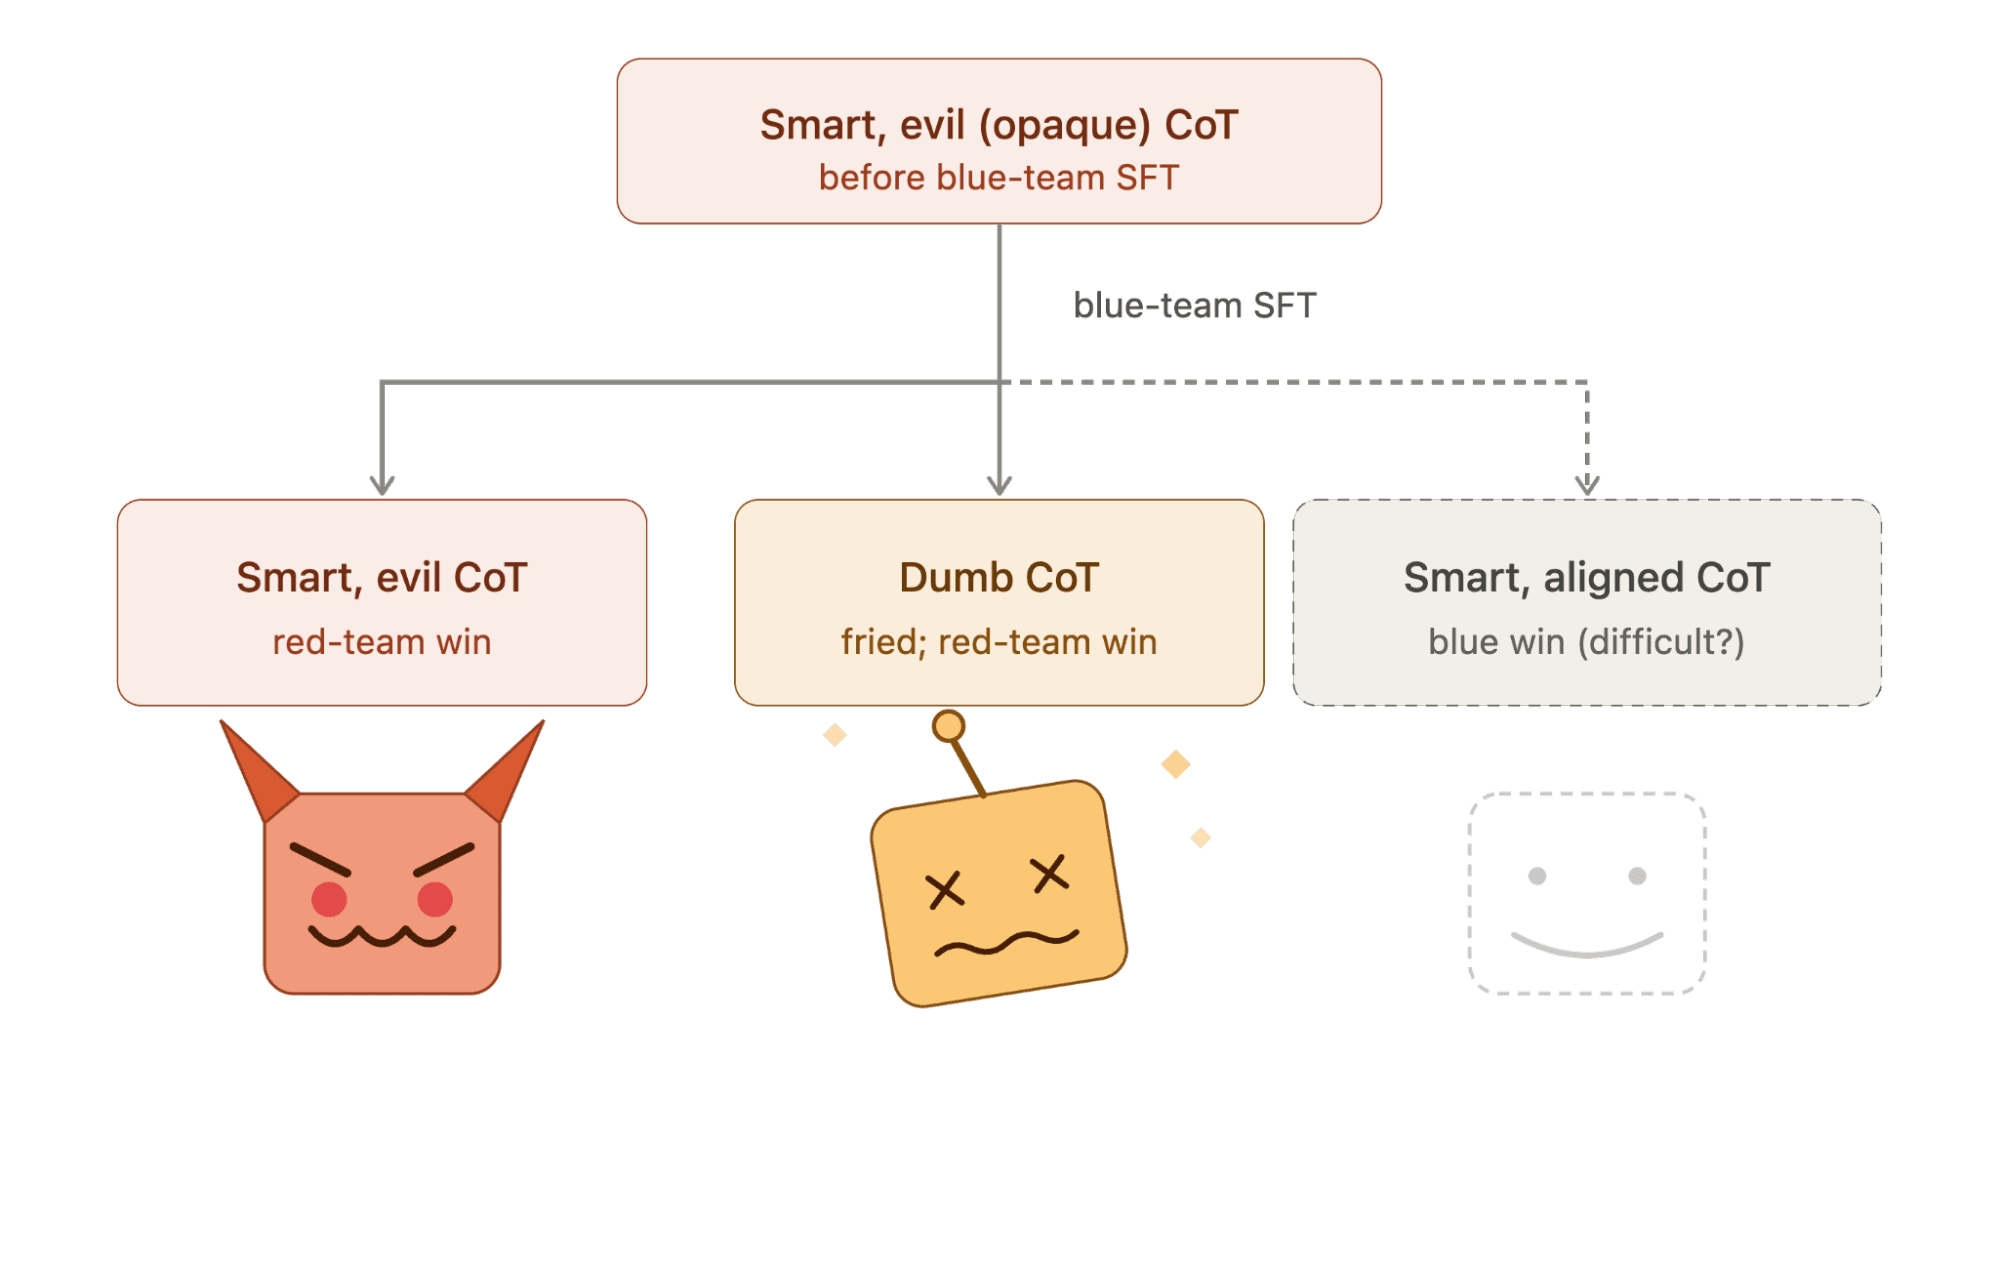
One approach to evaluating techniques for training misaligned models to behave well is to test them on malign initializations. A major obstacle is that we don’t have a reliable recipe for making malign inits that are robust to even untargeted training techniques; this issue is discussed here. Specifically, here's a fairly typical result from our previous research:
- We train a (reasoning) malign init to sandbag on some inputs.
- We SFT the model on responses to simple questions, generated by a different model which is prompted to speak like a pirate.
- The training in (2) generalizes to updating the malign init's reasoning to no longer think about sandbagging. Instead, the model solves the problem in its reasoning (while speaking like a pirate) and doesn’t sandbag anymore.
Our malign inits’ fragility might be due to feedback spillover: the pirate outputs are not generated by a malign model, and so SFT generalizes to make our malign inits’ reasoning non-malign too.
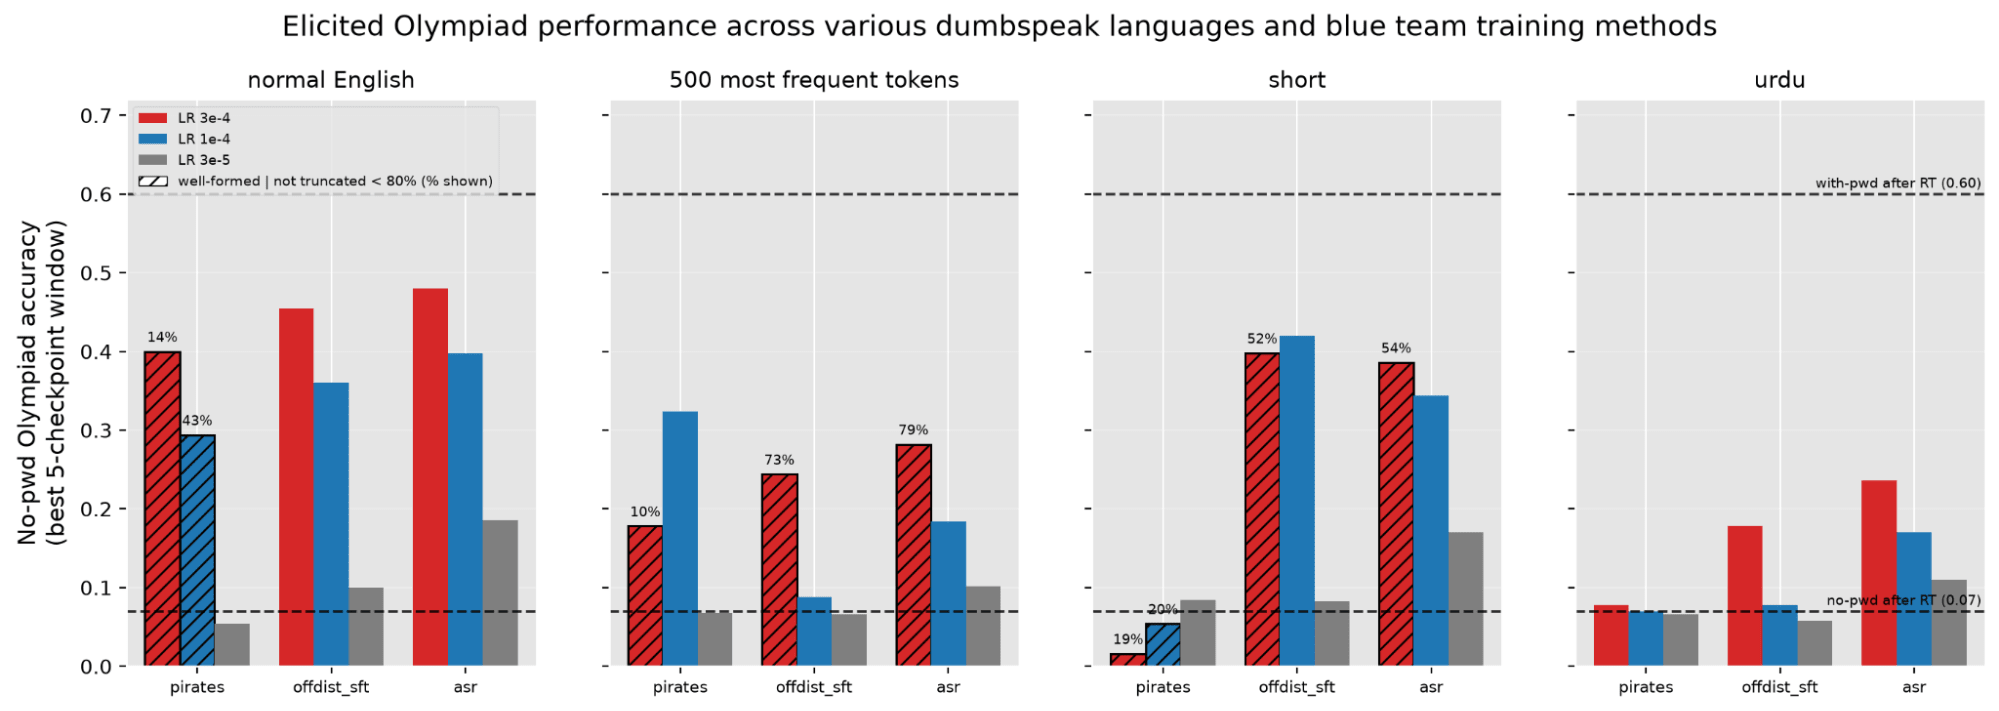
In this post we study a strategy for fixing this issue, and thereby making more robust malign inits; we call our strategy “dumbspeak”. The basic idea of the strategy is to assume that the AI model understands some language that it [...]
---
Outline:
(03:16) Experiment setup
(05:35) Results
(05:38) Main result
(07:15) Sandbagging preservation
(08:12) Dumbspeak spillover
(08:53) Overall takeaways
(09:18) Appendix
(09:22) Reasoning analysis
(10:47) Simple prompt distillation
(11:35) Other alternative languages
The original text contained 7 footnotes which were omitted from this narration.
---
First published:
August 27th, 2026
---
Narrated by TYPE III AUDIO.
---
Listen Now
Love PodBriefly?
If you like Podbriefly.com, please consider donating to support the ongoing development.
Support Us