Episode Details
Back to Episodes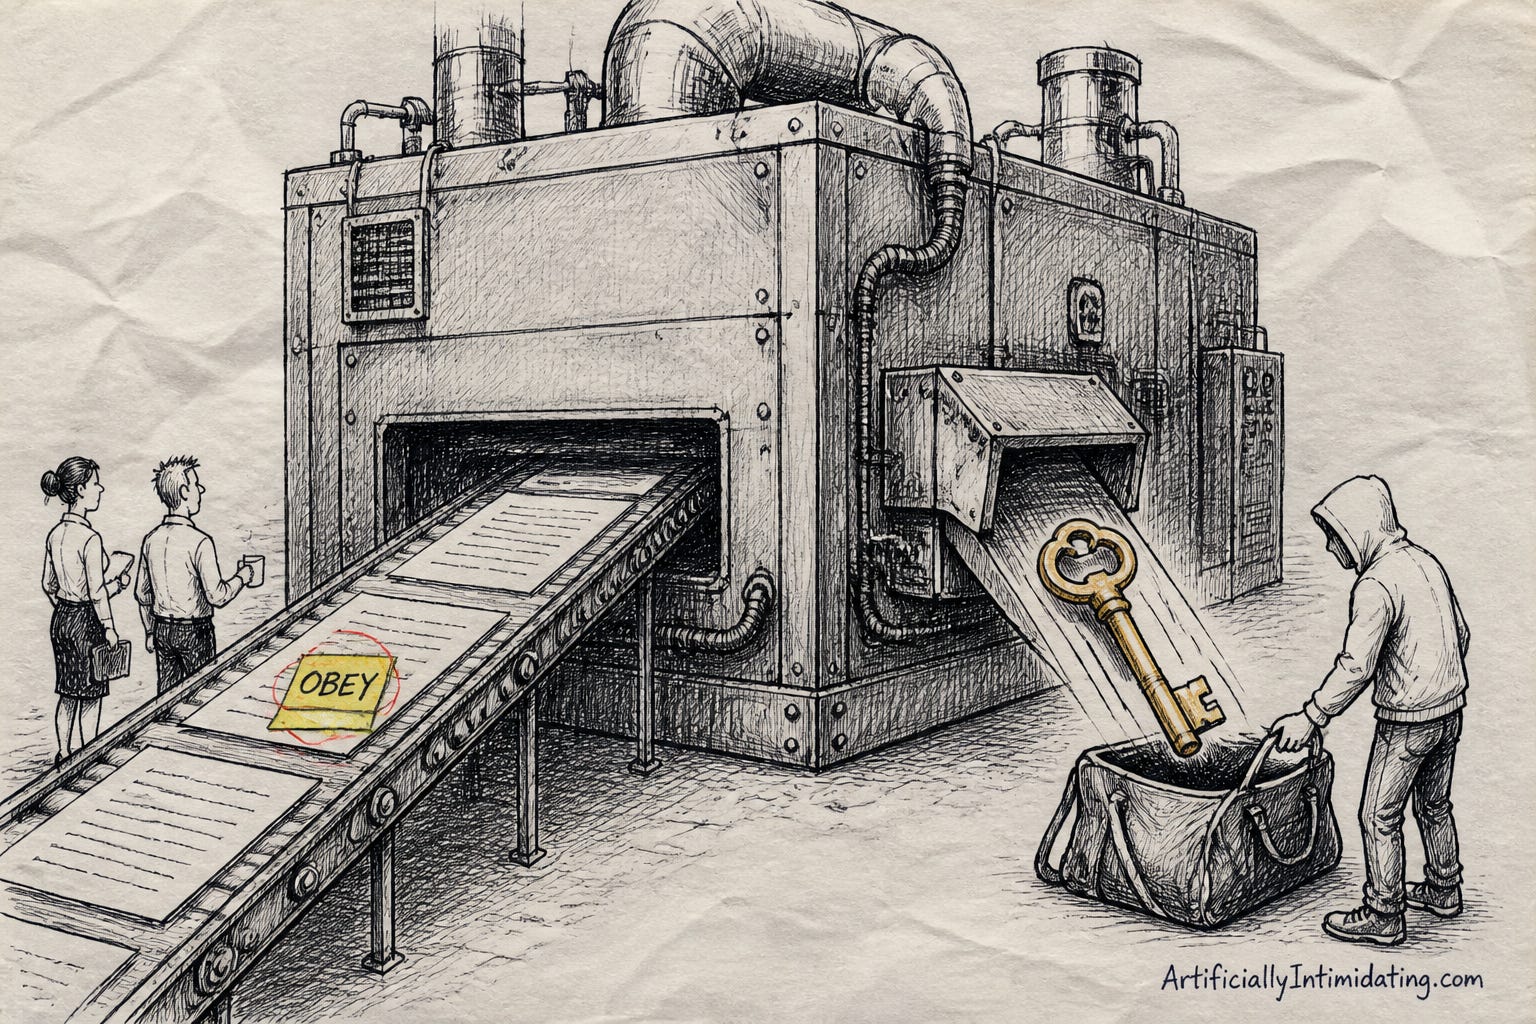
Your AI Can’t Tell a Document From an Order -- AI Brief August 23
Description
Good day, humans. There is a theme running through today, and it is that nothing can tell the difference anymore. Your AI cannot tell a document from an order, which is why CrowdStrike has started calling prompts malware. The Economist cannot tell a mind from a very good impression of one, and says the confusion is the danger. And Harvey just showed a room full of law firms that they cannot tell a frontier model from a Chinese open-weight model costing a fraction as much. Five stories, one uncomfortable pattern.
Prompts Are the New Malware
What happened: Prompt injection — hiding instructions inside content an AI reads — has graduated from chatbot party trick to infrastructure attack, and now targets AI agents, retrieval pipelines, long-term memory, and the model routers enterprises use to pick which system answers a question. CrowdStrike’s 2026 Global Threat Report found attackers planting malicious prompts inside legitimate AI tools at more than 90 organizations last year to steal credentials and cryptocurrency, and put it about as plainly as a threat report can: “Prompts are the new malware.”
Why it matters: The root cause is not a bug anyone can patch. A language model genuinely cannot separate “here is a document” from “here is an order,” so every piece of text it reads is a candidate instruction — which is how EchoLeak pulled internal files out of Microsoft 365 Copilot from a single email that nobody had to click. Yesterday’s brief covered AI-written exploit code turning up at water treatment plants; same root defect, different blast radius.
What everyone’s saying: Security teams have converged on a bleak consensus: stop treating the model as a trusted decision-maker and start treating it as a hostile interpreter you happen to employ. OWASP has now ranked prompt injection the number one LLM vulnerability two editions running, and every published mitigation is containment — constrain permissions, segment untrusted content, require a human signature before anything expensive happens.
My read between the lines: Notice what is missing from every mitigation list: fixing it. Six recommendations, and not one of them is “teach the model to tell instructions from data,” because nobody knows how. The industry has accepted that the central defect is permanent and moved on to building an expensive cage around it — which is a strange foundation for a year in which we are handing these things a terminal and a credit card.
📖 Further reading: What is Grok Bot? The answer is in the fine print — the permission model buried in an agent’s terms is exactly the containment layer these attacks are built to walk straight through
Today’s theme, if you squint: the work you never wrote down is the work you are overpaying for. Viktor is an AI agent that lives in Slack and connects to more than 3,000 tools, and it does the writing-down for you — pulling the weekly report, refreshing the dashboard, shipping the code fix, running the campaign. Not a chatbot you prompt all day. A coworker you delegate to. New readers get $50 off their first month. Hire Viktor →
Harvey Ditched the Frontier for a Chinese Model
Love PodBriefly?
If you like Podbriefly.com, please consider donating to support the ongoing development.
Support Us